AI Cite Check.
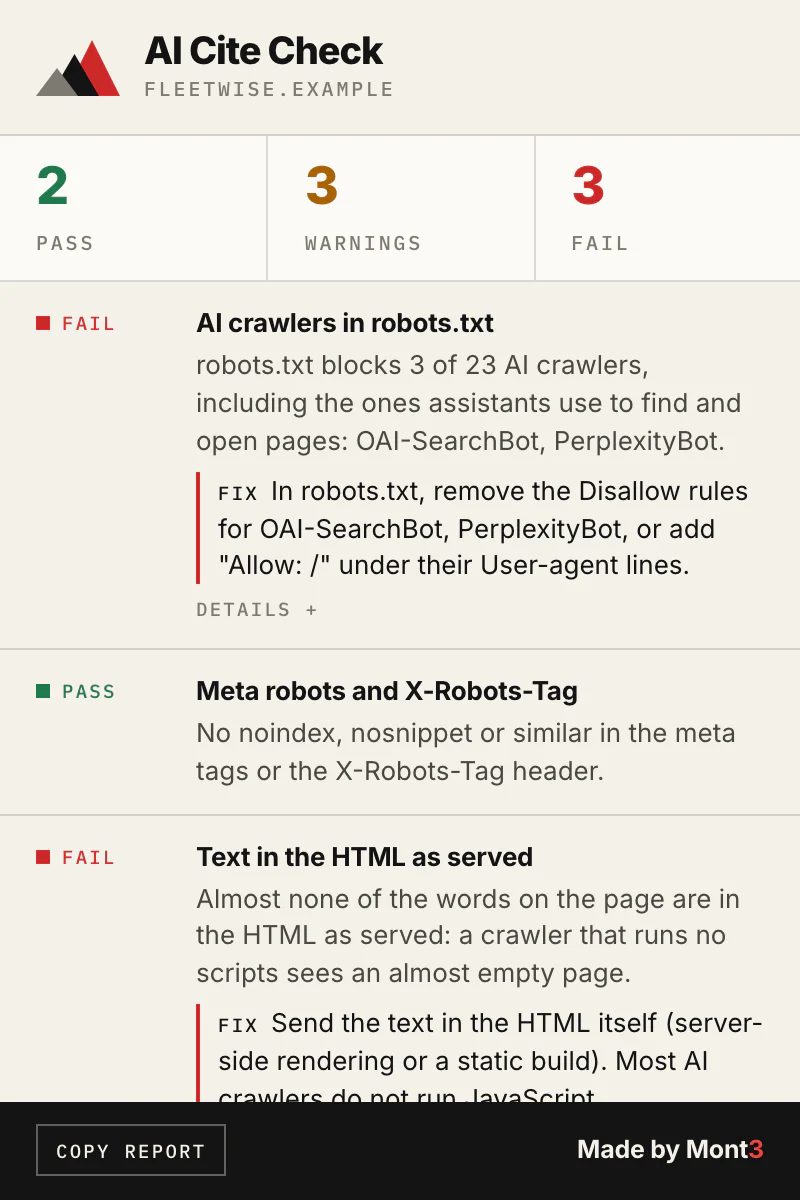
A free Chrome extension made by Mont3. It tells you whether the page in your tab can be read and cited by AI assistants: ChatGPT, Claude, Perplexity, Gemini, Copilot and others. Click the icon on any page and you get eight checks, each marked pass, warning or fail, with one plain sentence on how to fix what is wrong.
Eight checks,
one click.
Open a page of your site and click the icon. The report names what keeps the assistants out, and every problem comes with its fix.
AI crawlers in robots.txt
Whether 23 AI crawlers may fetch the page: blocking one that searches or fetches is a fail, blocking only training crawlers is a warning.
Meta robots and X-Robots-Tag
Instructions that keep a page out of answers, such as noindex, nosnippet and max-snippet:0, in the meta tags and in the response header.
Text in the HTML as served
Fetches the address again with no cookies and runs no scripts, then compares its words with the rendered page: 85% or more is a pass, under 50% is a fail.
Structured data
JSON-LD that is present and valid, an organisation with a name, a url and sameAs links, and FAQPage markup when the page has two or more question headings.
llms.txt
A text file at /llms.txt that opens with a "# Name" line: a missing one is a warning, not a fail, because it is a proposal and not a standard every assistant reads.
Sitemap
Finds the sitemap from robots.txt (or /sitemap.xml, /sitemap_index.xml), follows sitemap indexes and .gz files, and looks for the page in it.
Title, description, h1 and canonical
A title, a meta description, exactly one h1 and a canonical link, in the HTML as served: items that only a script adds are a warning.
Who is speaking
Whether the company name (from the structured data, og:site_name or the domain) is in the visible text, within the first 200 words or in the headline.
The 23 AI crawlers
it looks for.
The names a robots.txt has to let in. Each one was read on its vendor's own documentation on 15 Nov 2026, and every token links to that page.
| Vendor | Token in robots.txt | Role |
|---|---|---|
| OpenAI | OAI-SearchBot |
Search index |
| OpenAI | ChatGPT-User |
Fetch on request |
| OpenAI | GPTBot |
Training data |
| Anthropic | Claude-SearchBot |
Search index |
| Anthropic | Claude-User |
Fetch on request |
| Anthropic | ClaudeBot |
Training data |
| Perplexity | PerplexityBot |
Search index |
| Perplexity | Perplexity-User |
Fetch on request |
Googlebot |
Search index | |
Google-Extended |
Training data | |
| Microsoft | bingbot |
Search index |
| Apple | Applebot |
Search index |
| Apple | Applebot-Extended |
Training data |
| Meta | meta-externalfetcher |
Fetch on request |
| Meta | meta-externalagent |
Training data |
| Amazon | Amzn-SearchBot |
Search index |
| Amazon | Amzn-User |
Fetch on request |
| Amazon | Amazonbot |
Training data |
| Mistral | MistralAI-Index |
Search index |
| Mistral | MistralAI-User |
Fetch on request |
| Mistral | MistralAI-Training |
Training data |
| DuckDuckGo | DuckAssistBot |
Search index |
| Common Crawl | CCBot |
Training data |
Googlebot and bingbot are in the list because Google's AI Overviews and Microsoft Copilot answer from the Google and Bing search indexes.
Left out on purpose, because no vendor page documents them: Claude-Web and anthropic-ai (not on Anthropic's page), Bytespider (no ByteDance page) and cohere-ai (Cohere's page says it runs no crawler).
Private by design.
No data is collected. There is no account, no analytics and no tracking. The extension gets access to a tab only when you click it, and the only requests it makes go to the site in that tab: its robots.txt, its llms.txt, its sitemap and the page itself. Nothing is sent to Mont3 or to anyone else.
What it cannot see.
- It fetches the page with your browser's user agent. A site that sends different HTML to bots, or blocks them at the firewall, looks fine here.
- It reads robots.txt as written. Some crawlers that fetch a page because a person asked (ChatGPT-User, Perplexity-User, meta-externalfetcher) say they may not follow robots.txt.
- On very large sites it opens at most 12 sitemap files, and says so when it stops.
- A sitemap on another host cannot be read from the page (the browser forbids it), and is reported as a warning.
How to be cited by AI.
AI Cite Check tells you whether a page can be read and cited. Whether it does get cited also depends on what the page says and on who else talks about you. That part is the service Mont3 sells: we help companies get cited by AI.